Every network platform now ships an AI assistant, and the demos all look the same. Type a question, get an answer, applause. What the demos skip is the part that decides whether the answer is any good: the data underneath.
Ask an agent to investigate a slow application and it has to do what you would do. Find the affected hosts, pull the traffic for the window, check the path, compare against normal. Whether it can do any of that depends on what the telemetry looks like when the agent gets there. And this is where a thirty-year-old protocol family turns out to have been ahead of its time.
What an AI needs from data
Language models and agents work more reliably with structured data. Give an agent a table with typed, named columns and it can filter, aggregate, and pivot with confidence, because every field means one defined thing. Give it a blob and it has to parse before it can reason, and parsing at scale is slow, expensive, and error-prone.
In the last installment we walked through what a modern flow record holds: application identity, usernames, on-wire performance metrics, NAT translation state, path and policy fields, and Layer 7 metadata. Every one of those is an IPFIX Information Element with a registered ID, a data type, and a defined meaning in an IANA registry. In other words, a schema.
That schema is the shape AI systems want. A flow record is a database row an agent can query directly. A packet capture is a file it has to interpret first.
What that looks like in an investigation
Say the ticket reads "checkout is slow for the Denver location." An agent working from rich flow records can run the whole chain itself. Pull flows for the Denver subnet in the affected window. Group by application to confirm which service degraded. Check round-trip time and retransmit counts on those flows to see whether the delay sat on the network or the server. Pivot to the interface pair involved and compare against the baseline. Every step queries fields with defined meanings. That makes the agent's reasoning checkable. You can look at the same fields and confirm it.
Now hand the same agent a directory of packet captures. Before it can answer anything, it has to find the right capture files, decode them, reconstruct sessions, and classify traffic. Each of those steps costs time and compute, and each one is a place to go wrong. The agent isn't smarter on one dataset than the other. The difference is that flow hands it queryable fields, while packet capture burns processing time and enormous token counts before the first real answer.
The richer your templates, the more questions an agent can answer without escalating to you. An exporter that sends application names, performance fields, and identity gives the agent the same pivots a senior engineer uses. An exporter still sending the bare five-tuple gives it who talked to whom, and that's where its investigation stalls, same as yours would.
Whose AI, whose data
The next decision is bigger than it looks. The easy path is the assistant your vendor hosts: their model, their prompts, their platform, and your data flowing through their pipeline. It works, and it locks the intelligence to the tool.
The other path is pointing the AI your team already trusts at your own network data. Two decisions hide in that sentence, and they're worth separating. The first is which assistant asks the questions. Your team probably already has agents and assistants it trusts, with your access controls and your workflow around them; what they lack is a way to see the network. That is the gap the Model Context Protocol closes. MCP is an open standard that lets an AI assistant query an external system through a defined interface. MCP does not host the model. Scrutinizer keeps the flow records in your deployment, but the connected assistant and model determine whether prompts or retrieved context leave it. The second decision is where the model runs. Plixer supports managed inference or a customer-controlled OpenAI-compatible endpoint that can keep the loop self-hosted, sovereign, or air-gapped.
The network's answers shouldn't be a feature of somebody's chat window. They should be a data source any of your agents can reach.
Where Plixer fits
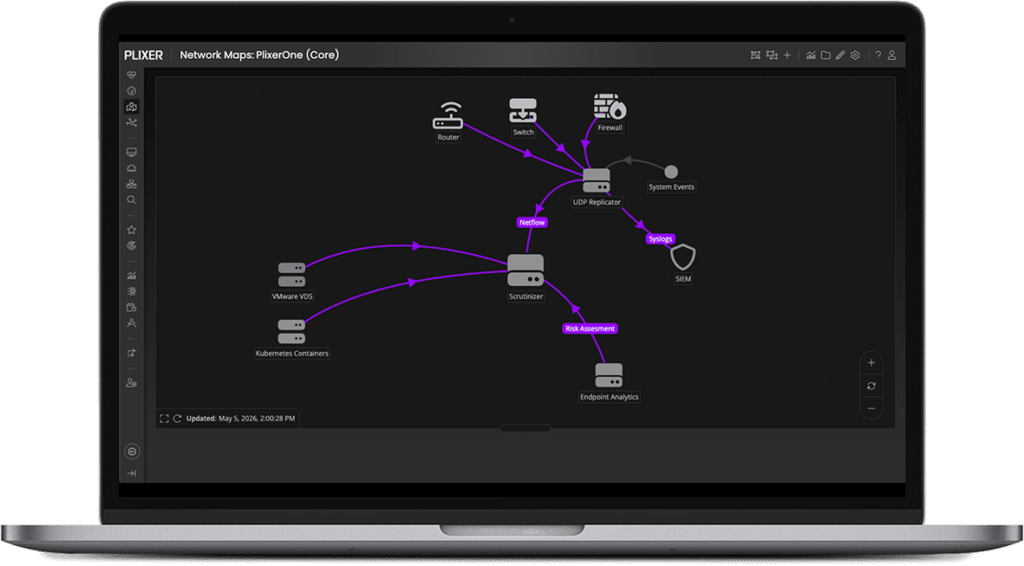
Scrutinizer has an MCP server. Connect it and the AI your team already uses can query your flow data directly — top talkers, application performance, host conversations, anomalies — the same questions you'd ask in the product, asked in your own tools. Your AI, your model, on your own network data, and no sensors to buy to feed it, because the data is the flow your routers, switches, and firewalls already export.
For teams that want investigation built in, Plixer AI adds agents inside the product. AI Insights correlates flows, builds the timeline, names the likely cause, and recommends a next step, ranked by observed risk and impact. The AI Assistant answers questions conversationally in the interface. Both work the same way: the investigation runs on its own; changes don't.
Either way, the foundation is the same from part one of this series. The reporting an agent can do depends entirely on what your exporters send, so the template audit we recommended there is also the most useful AI project you can run this quarter, and it costs nothing but configuration you already own.
The catch
An agent is only as good as the schema it queries, and three things degrade the schema.
Thin templates. If your exporters send the five-tuple, your agent investigates with the five-tuple. Enable the fields that answer the questions you ask most, one exporter at a time, and confirm that each decodes end to end.
Undecoded fields. A collector that drops an element it doesn't recognize is silently narrowing what your AI can see. Ask what yours does with unfamiliar fields, because the agent won't know what it's missing and neither will you.
Ambiguous meaning. Vendor-proprietary fields with no published definition force the same guesswork on an agent that they force on you. Prefer registered elements where you have the choice.
Key Takeaways
- AI agents reason well over typed fields with defined meanings, which is exactly what NetFlow v9 templates and IPFIX Information Elements provide.
- A flow record is queryable the way a database row is. A packet capture has to be parsed before an agent can use it.
- Template richness sets the ceiling on what an agent can investigate. Five-tuple in, five-tuple answers out.
- MCP lets the AI your team already trusts query your network data directly, instead of locking the network's answers inside a vendor's assistant.
- The same template audit that improves your reporting improves your AI.
Next Steps
Connect an MCP-capable assistant to the Scrutinizer MCP server and ask it something you'd normally build a report for. Which application used the most bandwidth on the WAN link yesterday? Which hosts talked to a subnet they'd never touched before? Judge it the way you'd judge a junior engineer: is the reasoning visible, and can you check the fields it used.
Frequently Asked Questions
No. The agents investigate and recommend; they don't reconfigure network devices at all.
No. The MCP server connects assistants to your Scrutinizer deployment and the data it already holds.
Then start there. An agent can't query fields your exporters don't send. The template audit from part one of this series comes first.
Any client that supports MCP can connect. Check your chosen assistant or agent framework for current MCP support.